Mixing Tips
De-Essing Without the Lisp: What Actually Works on a Harsh Vocal

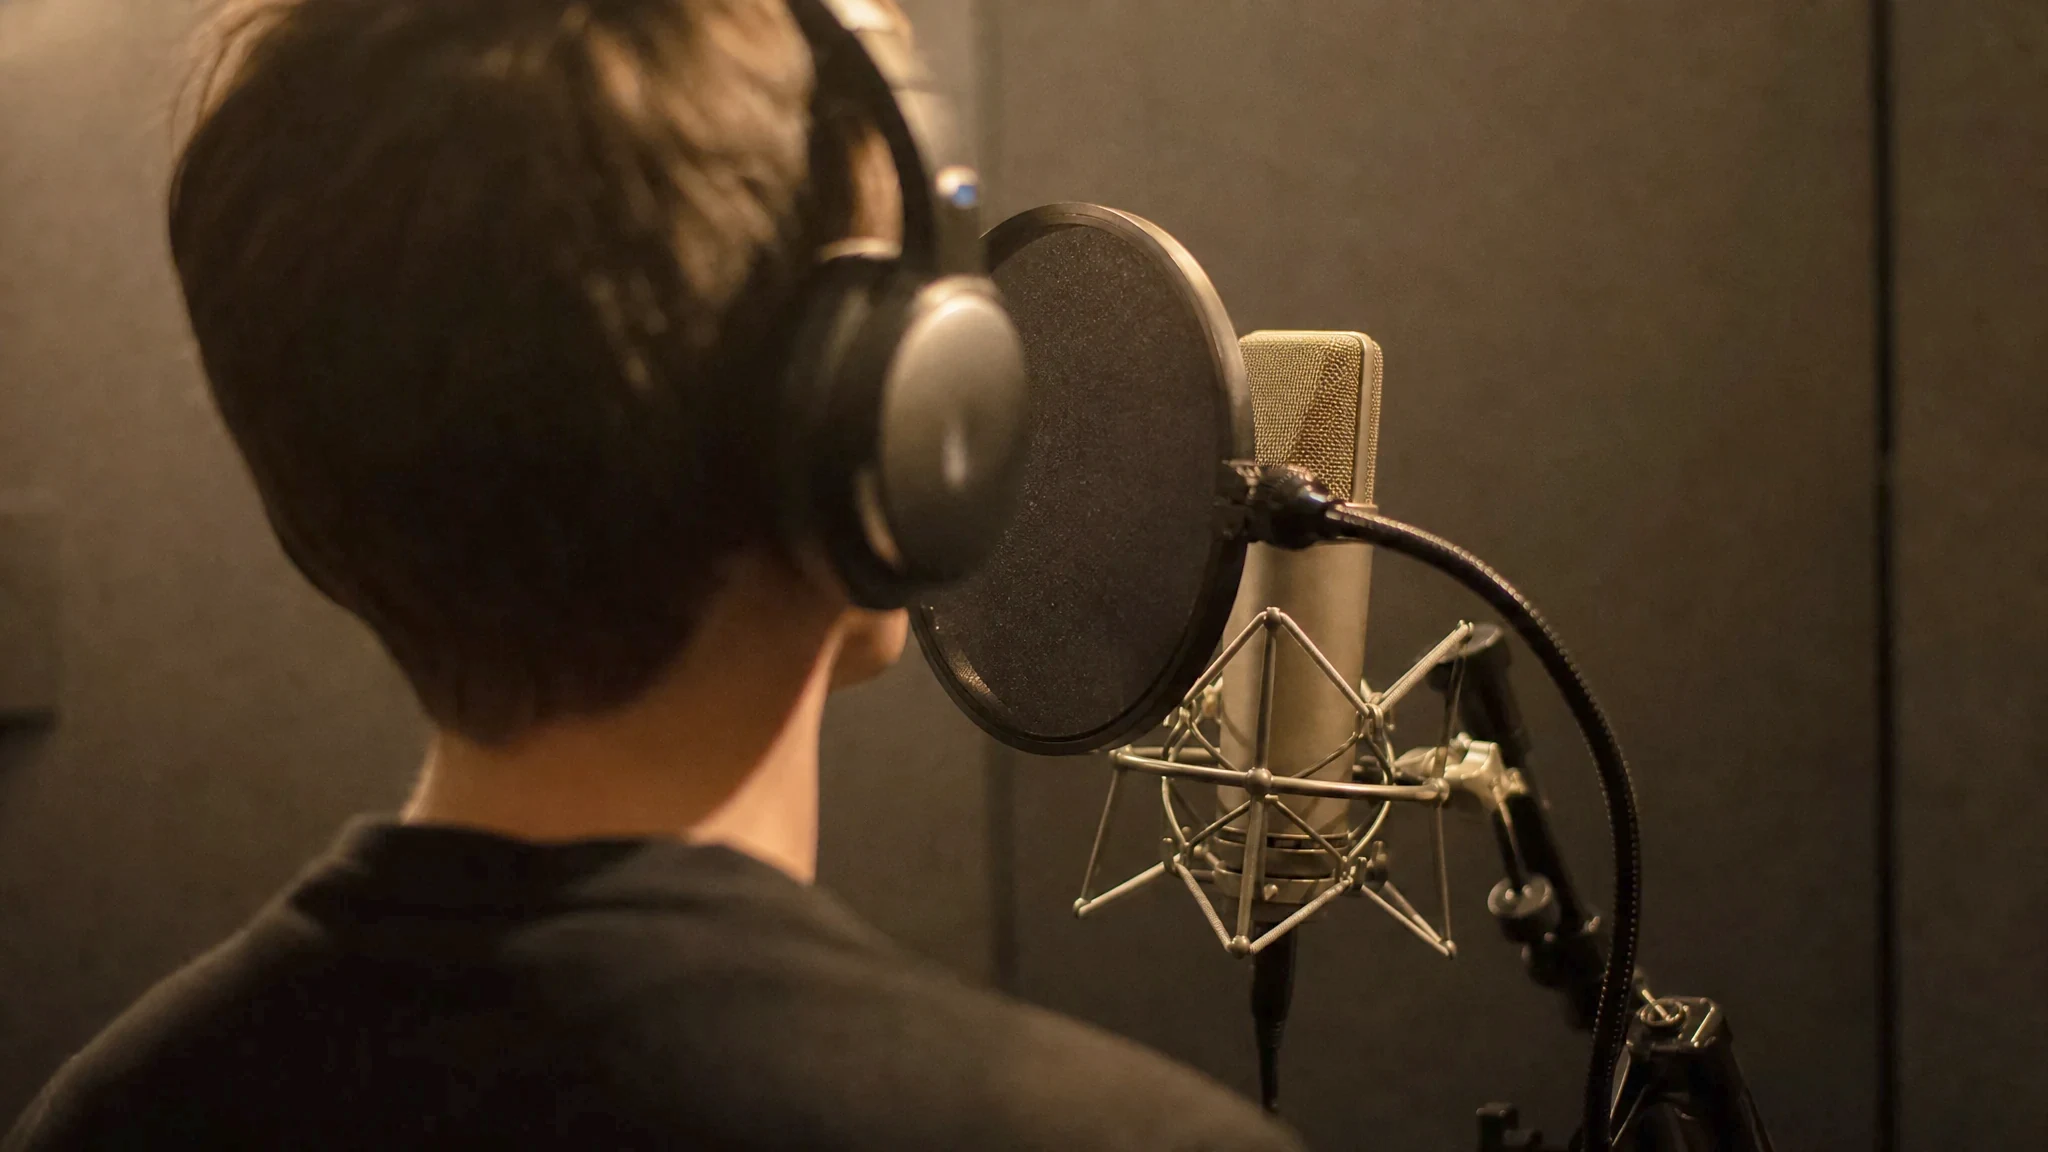
The singer was good. That was the problem. She had the kind of diction that makes a lyric land on the first listen, every consonant placed, nothing mumbled, and every single one of those consonants arrived at my converter like a struck match. I put a de-esser on the channel, pulled it down until the sting went away, and played it back to her. She listened to eight bars, made a face, and said the thing I have heard a dozen times since: why do I sound like I have a cold?
She was right, and it took me longer than it should have to work out why. I had traded one obvious problem for a less obvious one, which is the trade almost everybody makes on the first pass, usually within the first minute of noticing the problem at all. The sting was gone. So was a chunk of the reason her voice sounded like her voice.
An s is not a frequency
The mental model that causes the damage is the one that treats sibilance as a band, and almost every tutorial teaches it that way. Find the offending frequency, cut the offending frequency, problem solved. It is a tidy idea and it does not survive a real vocal. What leaves a mouth on an s is a burst of noise, not a tone, spread across a wide stretch of spectrum rather than parked on one frequency. Where its energy concentrates depends on the singer, and it moves: a female voice often sits around 7 to 9 kHz, a male voice lower, sometimes 5 to 6, and the same person will shift by a kilohertz or more between an s, a sh and a t in the same line.
It also moves in level, violently. In an ordinary sung phrase the sibilants can sit 8 to 12 dB above the vowels around them, and then the next line comes in softer and they sit 4 dB above. So the thing you are trying to catch changes both its address and its loudness several times a bar. A fixed EQ cut cannot follow that. It takes the same amount out of the word sky and the word alone, and the second one did not need it.
That is the case for dynamic treatment in one sentence: the target moves, so the tool has to move with it.
Three ways it turns into a lisp
Assume you already moved to something dynamic, and it still sounds wrong. There are three reasons, and they are worth separating, because the fix is different for each and guessing wastes an afternoon. The first is bandwidth. A de-esser working over too wide a range does not just remove the hiss on the s, it removes the air off the vowel on either side of it, and the ear reads that loss of top as a change in the voice rather than a change in the consonant. You hear a different singer, not a quieter s.
The second is release. If the gain comes back slowly, the reduction that started on the consonant is still partly in place when the vowel behind it begins. The consonant is fine. The syllable after it has a hole in the top, and that hole is exactly what a head cold sounds like. Anything much past 150 ms starts to bleed into the next sound on a fast lyric.
The third is the threshold, and it is the one that catches people out on a full take rather than a loop. You set it on the loudest line in the chorus, where the sibilants are enormous. Then the second verse comes in 5 dB quieter, the s sounds no longer cross the threshold, and half the song goes untreated while the chorus gets hammered. Or you set it on the verse and the chorus gets flattened. One static threshold across a take with real dynamic range will always be wrong somewhere.
The boring fix works, which is why nobody does it
Before any of that, there is clip gain. Zoom in, find the sibilants that actually hurt, and pull each one down 3 or 4 dB by hand. It is manual, unglamorous, and on a three minute song it is twenty minutes of work, because you are not treating every s in the take. You are treating the six or eight that jump out.
The reason it beats every processor is that you are not making a rule. A de-esser has to decide, from a threshold and a time constant, what counts as too much. You already know which ones are too much, because you can hear them. You apply the reduction to those and leave the rest of the vocal untouched, which means the air, the breath and the top of the vowels all survive intact.
It also fixes the threshold problem for free. Quiet verse, loud chorus, doesn't matter: you judge each event on its own. Do this first and whatever follows has far less to do, which means it can be set gently enough that nobody hears it work.
An opto compressor that already leans this way
Here is something that surprised me when I went looking through the circuit rather than the manual. The original LA-2A had a small network in its detector path whose job was to make the compressor more sensitive to high frequencies than to low ones, so it would ride the top of a signal harder. It survives in the VLA-2A Mark II as the Emphasis control, and it is a modelled fourth-order network with the component values of the original rather than a shelf someone drew.
Running the numbers out of the transfer function is more interesting than the knob suggests. At the factory setting of 0.8, the detector is 8.6 dB more sensitive at 8 kHz than at 1 kHz. Turn it to 0 and that falls to half a dB, which is to say the compressor goes flat and hears the whole voice equally. At 0.4 you get about 4.5 dB. So the plugin ships, out of the box, already biased toward the part of the spectrum that sibilance lives in.
That is not a de-esser and I would not sell it as one. The reduction is still broadband, so when it pulls, the whole voice moves. But it explains something people notice and cannot account for: an opto compressor set gently often makes a bright vocal sit better than a flat-detector compressor doing identical work. It is not the opto cell being magic. It is a filter in the sidechain that was there in 1965.
When to build one, when to buy one
If clip gain has taken the edge off and something is still needed across the whole take, you can make a de-esser out of a compressor you already own, provided it has an external key input. This is not a workaround or a clever trick, incidentally. Every hardware de-esser ever built was a compressor with a filter in front of its detector, so building one this way is not an approximation of the real thing, it is the real thing with the parts left visible. Both the BlackAsh SC-5 and the VLA-FET have one; the blue SC-5 does not, which trips people up because the panels look so similar. Feed the key a copy of the vocal with the lows stripped and the top pushed hard, and the compressor becomes deaf to everything except the consonants. I wrote out the settings I use for that in the piece on the external input, so I won't repeat them here.
What it cannot do is act on one band alone. Past about 3 dB of reduction you hear the whole vocal duck, and a take needing 6 dB wants a split-band tool instead. Telling those apart takes five seconds: pull the reduction down until the s behaves, then listen to a vowel. If the vowel moved, you are asking a broadband tool to do a split-band job.
Where the s came from
All of this is repair work, and the cheapest repair is the one you make before recording. A large diaphragm condenser pointed straight at a singer's mouth from eight inches away is the standard setup, and it is also the arrangement that collects the most sibilance of any you could choose, because the high frequency energy of a consonant leaves the mouth in a narrow forward beam while the body of the voice spreads out in every direction. Rotate the capsule fifteen or twenty degrees so the singer is slightly off-axis and a good part of the problem never reaches the converter.
The pop filter matters too, and not for the reason it is usually sold. Placed flat against the path it stops plosives and does very little else. Angled, so the singer sings across it rather than through it, it nudges the whole delivery a few degrees off-axis without anyone having to think about mic technique mid-take.
And then there is the singer, who will often solve it faster than any of it. Ask for the line again with the consonants softened. Good vocalists can do that on request, and it takes one pass.
The order I work in
Clip gain the handful of sibilants that actually hurt, which on most takes is six to eight of them. Listen again, because more often than people expect, that is the end of it. If something is still needed, compress with a detector that leans toward the top rather than flat, which on an opto is where the Emphasis control earns its place. If the vocal still fights you after that, build the sidechain de-esser and keep it under 3 dB. Reach for a split-band tool only when a vowel moves before the s behaves.
What I would not do is start at the bottom of that list. A de-esser across the channel before anything else is a rule applied to a take you have not properly listened to yet, and it is how a good singer ends up sounding like she has a cold.
Both the VLA-2A Mark II and the BlackAsh SC-5 run as full fourteen day trials. Put one on the next bright lead you get sent, and set the compression by ear before you touch anything labelled de-esser.
Add a comment
You need to be logged in to add comments.